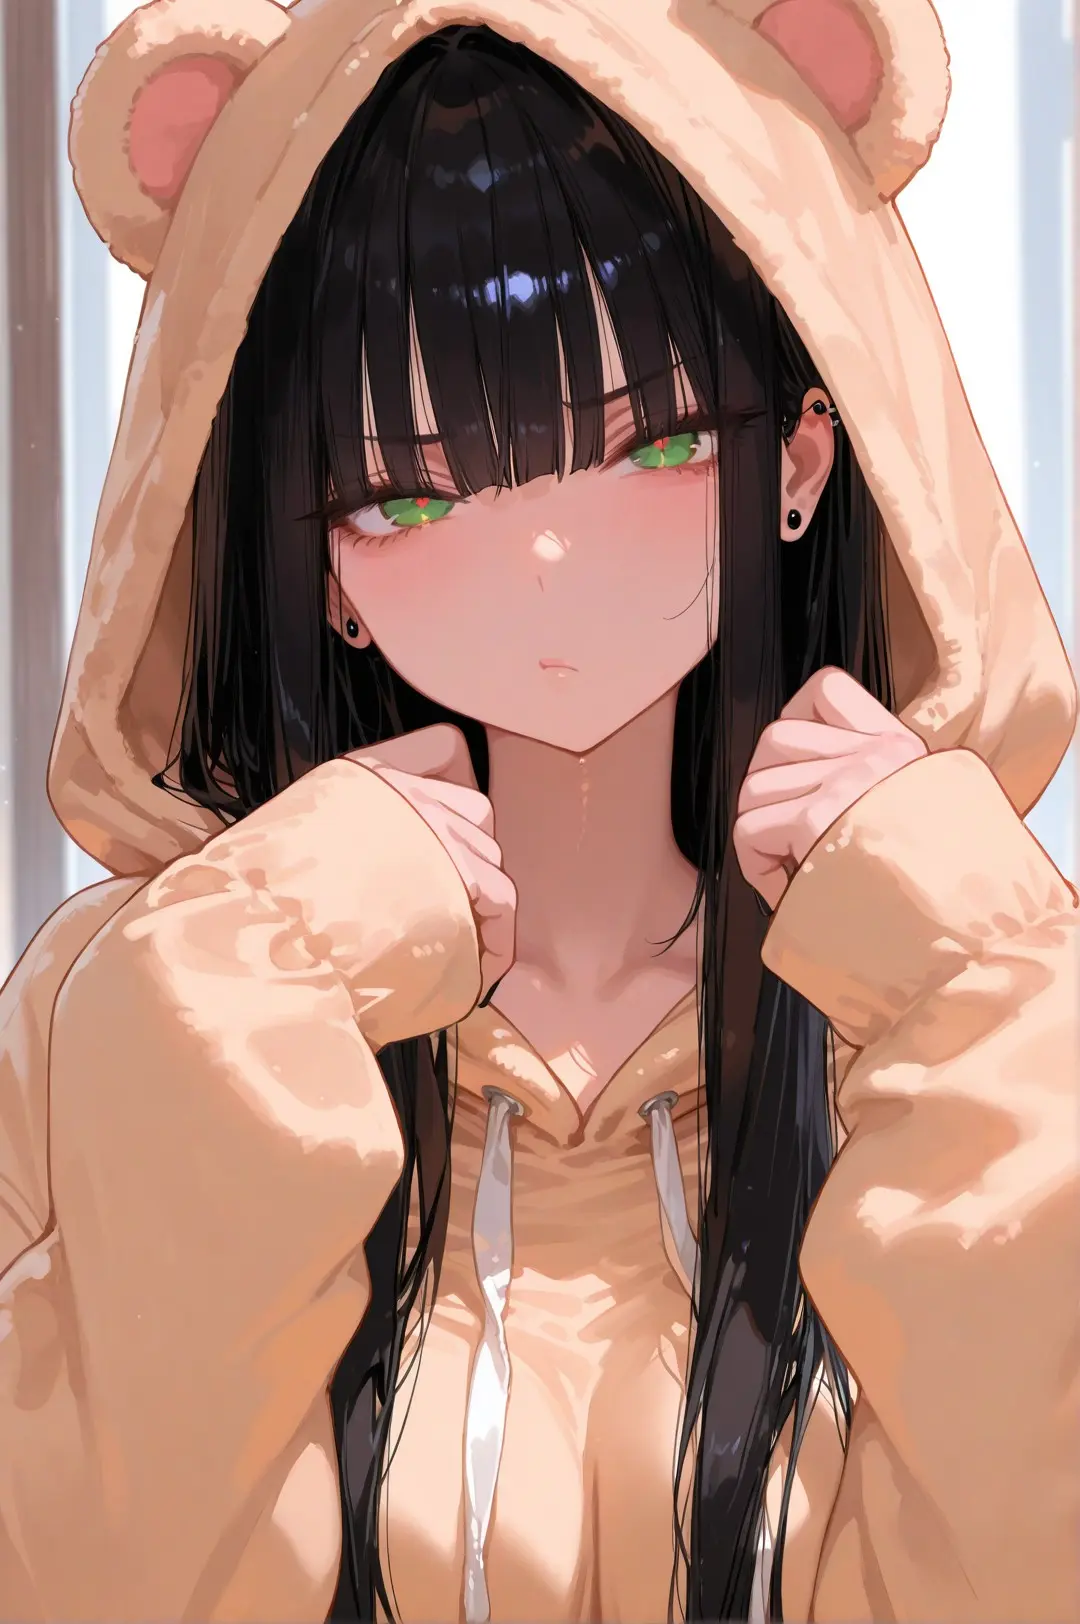
Generate character art in any style.

Type a prompt, pick one of fifty models and get a batch back in seconds. Or hand the brief to K Agent and let it plan, write and render dozens of scenes on its own.

Prompting

Direct a whole series from one brief.

Give AutoGen a character and a scenario. It plans dozens of distinct scenes, writes a fresh tag prompt for each one and renders them in sequence while you do something else.

You can edit the plan before anything renders and steer the run while it works. Anchor tags keep the character the same from the first image to the last, and a run of up to 50 batches downloads as one ZIP.

Try AutoGen
Batch 1/3
PROMPT
1girl, solo, silver_hair, red_eyes, pointy_ears, elf, leaning_forward, dark_room, candle, masterpiece
Batch 2/3
Prompting
Batch 3/3 queued

Bring your own models and LoRAs.

Paste a CivitAI or Hugging Face link and the checkpoint lands in your library in seconds. LoRAs import the same way, and everything you bring appears in the model picker next to the built-in lineup.

Import a model
kammii.ai/gen
Paste a CivitAI or Hugging Face link
Models
Import model
KAI Illustrious v1
Kiwimix v3
Boleromix v2.9
Anima Base v1.0
LoRAs
Import LoRA
Red lili v0.5
Aesthetic Quality
Anima Nikke Style
Photo Background 2d

The generator, driven by chat.

K Agent is a chat that drives Image Gen for you. It picks models, sets sizes, runs batches, builds character cards and files the art on your account.

Type one sentence, get three images.

Type plain English into the chat. K Agent picks the model, sets the size, runs the batch on your account, and the results land in the conversation.

Ask for a change, watch the controls move.

Name a model and a look in the chat and the real setting panels open. The gallery scrolls to Kiwimix v3, Landscape gets picked and Quality mode retunes size and batch. They are the same controls you would tap yourself.

Ask it how it works.

Ask where the tags come from and it explains the Danbooru vocabulary and the alias index behind every prompt it writes, with its reasoning shown while it thinks.

One tap from image to character.

Pick the strongest result and ask for a card. Name, tags, definition and three greetings are written live in front of you, each greeting a full scene with its own image.

Queue more with a sentence.

Ask for two more batches and the agent queues both server-side. The first six images land while you watch, and rendering carries on even if you close the tab.

kammii.ai/gen/autogen
GLM 5.2
What should we make?
Make a silver-haired girl in a crystal crown and white lace dress on a sunlit balcony over the city
Thinking…
Switch the image model to Kiwimix v3, set the aspect ratio to landscape, and put it in Quality mode
Model Batch Mode ?

Each generation costs 0.5 credits regardless of quantity and quality.

Search models...
KAI Illustrious v1
KAI Illustrious v2
Amanatsu v1.1
Zuki Cute v6
JANKU v4.0
Boleromix v2.9
Kiwimix v3
Vixons v1.4
Image Size
Square
1024x1024
Portrait
832x1248
Landscape
1248x832
Banner
1536x640
W1080 H1624
Resolution Scale 1.05x
0.8x1.0x1.3x
Quality1.3x / 3 imgs
Balance1.05x / 4 imgs
Quantity0.80x / 8 imgs
1.8 / 6.0 MP
Images Per Batch
1
Set Kiwimix v3 · Quality · Landscape 1624x1080 · 3 images per batch
Where do the tags in these prompts actually come from?
Thinking… 0.0s
Checking how the prompt writer maps plain English onto the tag index… The vocabulary ships with an alias table for common phrasings

They come from Danbooru, the board whose tag vocabulary the anime models were trained on

nakednude
schoolgirlschool_uniform
looking_at_cameralooking_at_viewer

Kyrune keeps a local index of the most-used tags and their aliases, so plain English maps onto the exact strings the model knows

Create a character card for this character
Character card JSON PNG
Tags adult× royalty× high fantasy× court intrigue× mystery× adventure×
Definition
Scenario
Greetings 1/1
Queue two more batches: one at night on the rooftop, one in the rain
Generating
Night on the rooftop · Generating 3 images…
Queued
Waiting…
xHigh

Ask Adjust Explain Card Queue

More than fifty models. Nothing to install.

Illustrative SDXL checkpoints, Z-Image and FLUX.2. Switch between them in the model picker at any time.

Pictures from the community

Everything here was made on Kyrune by the people who use it. Each picture shows the prompt and the model behind it.

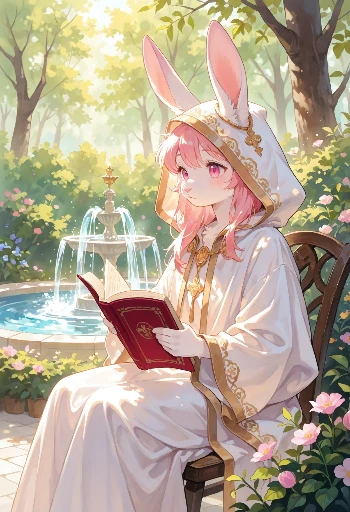
WAI Illustrious v17solo, 1girl, anthro rabbit, white fur, pink eyes, white cloak, hood up, white robe, gold embroidery, sitting, reading one book, garden background, fountain …
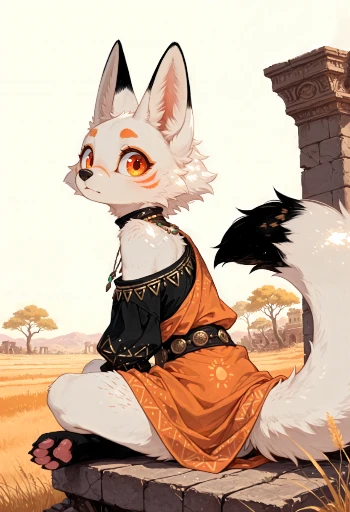
WAI Illustrious v17flat color, warm color palette, 1girl, solo, portrait, savannah, ruins, furry female, beautiful girl, cute girl, anthro, white fox girl, white fur, orange eyes …
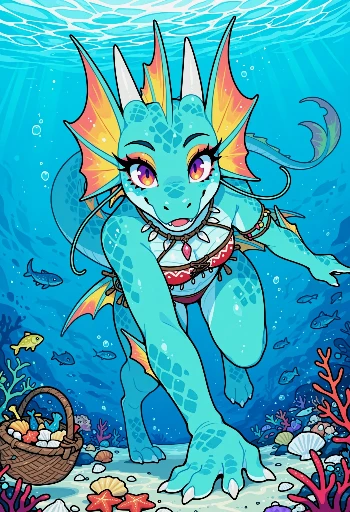
WAI Illustrious v17SmokyJai, flat color, black outline, dynamic view, solo, 1girl, feral dragon, furry female, dragon snout, scales, cute face, happy expression, long eyelashes …
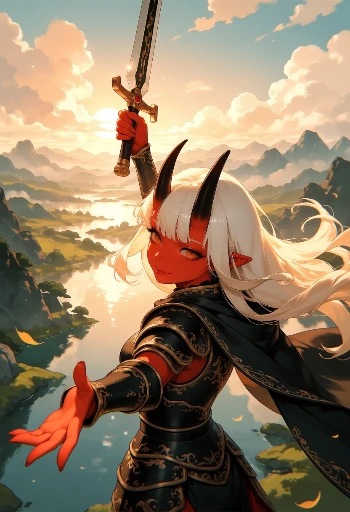
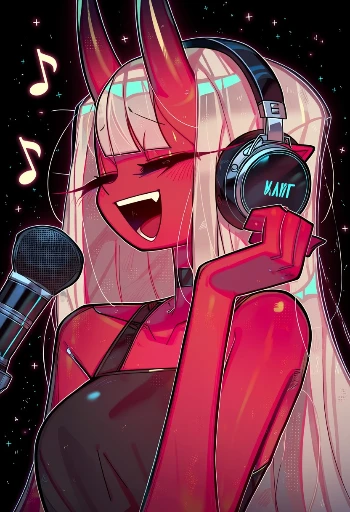
Anima Base v1.0cute girl, eyelashes, Aka-Oni, oni, oni horns, colored skin, red skin, smooth horns, black horns, straight horns, mature, from behind, holding sword, sword up …
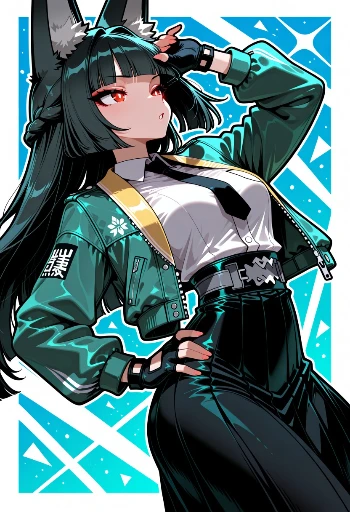
Hoseki - LustrousMixthick black outline, Rden_style_v4, kawaii pop art, 1girl, solo, hoshimi miyabi, animal ears, fox girl, fox ears, black hair, long hair, red eyes …
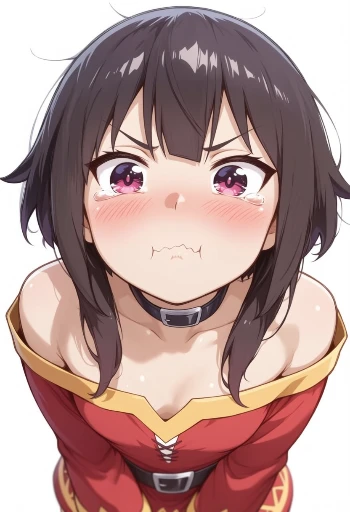
Pearly Hengetsu anima v1pearlymer, wavy mouth, blush, :i, tearing up, :t, pout, megumin konosuba

What each model draws like

Scroll through real pictures from Anima Base v1.0 and WAI Illustrious v17. When one catches your eye, open the model in the generator and start from there.

Anima Base v1.0

WAI Illustrious v17

Draw your favourite characters

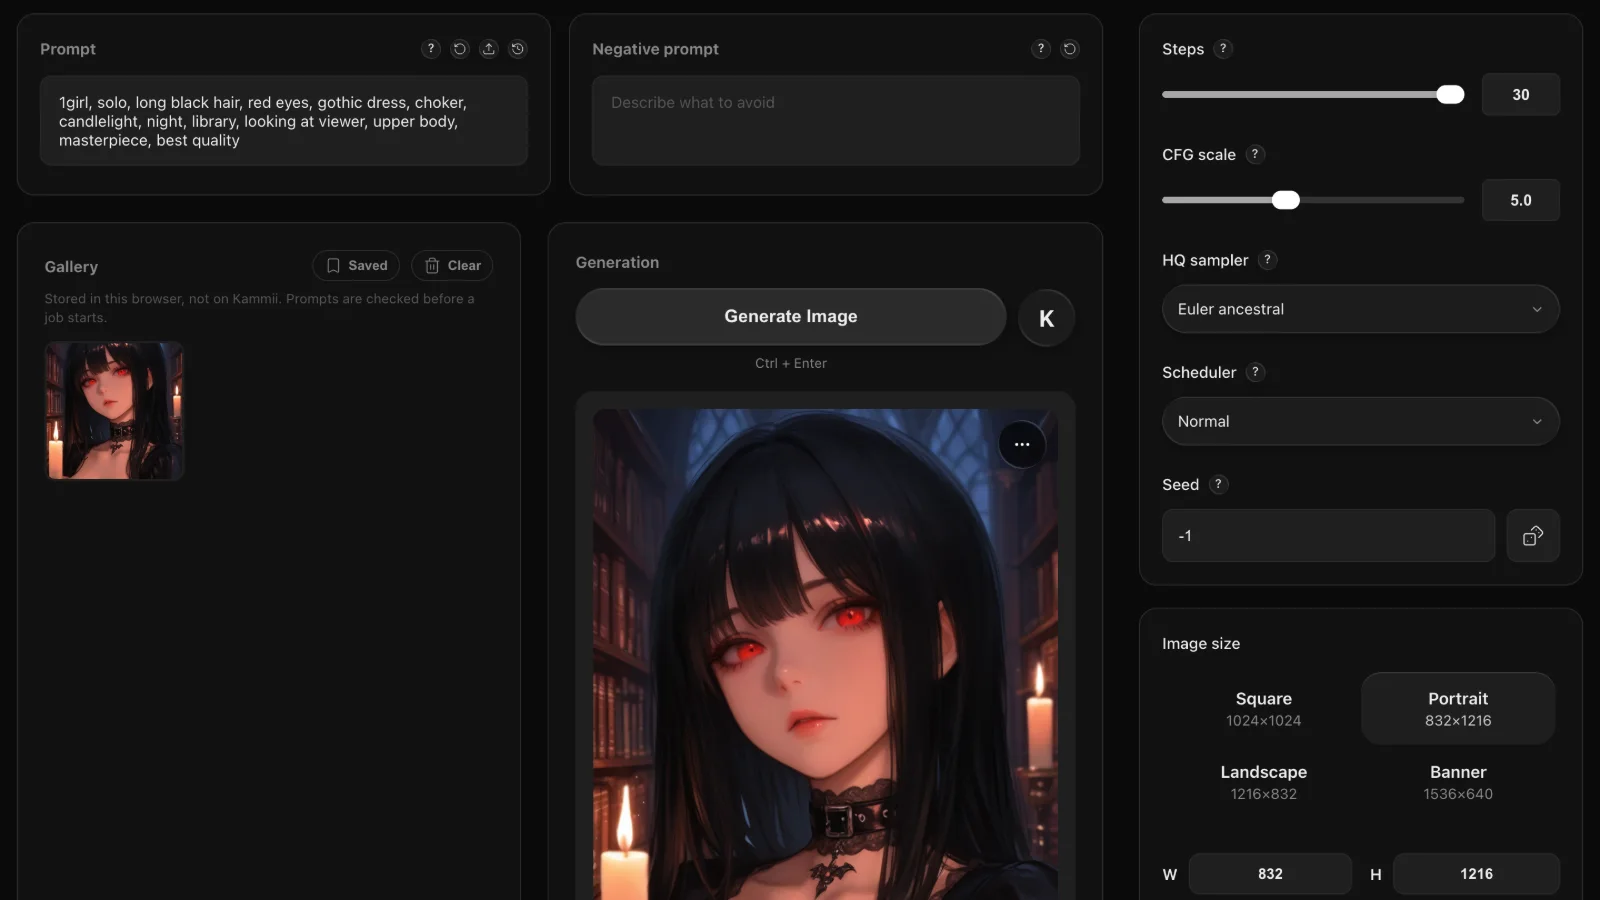
This is the generator you get when you sign in. Write what you want to see, pick a model, and your pictures appear in the middle of the page.

The Kyrune generator with a finished picture

Monthly plans.

Every plan includes the generator, the Roleplay API and Files hosting. Credits refill in full every 31 days and Dark Lord and King carry over what is left. Higher tiers run more K Agent batches at once, unlock the premium planning models and add profile looks, and you can cancel any time.

A rented 4090 costs about $0.40 an hour before you have installed anything. Supporter is $4.99 for a month of images.

Supporter
$4.99/ month
500 credits / month
~1,000 batches · up to 8,000 images
  • All image models
  • Batch and HQ modes
  • K Agent
  • Cloud gallery
  • A plan badge and profile looks
  • + 5 GB of Files hosting
Choose Supporter
Sponsor
$11.99/ month
1,500 credits / month
~3,000 batches · up to 24,000 images
  • K Agent runs 10 batches at once
  • Sponsor profile looks
  • + Unlimited Roleplay API messages
  • + 12 GB of Files hosting
Choose Sponsor
Dark Lord
$49.99/ month
10,000 credits / month
~20,000 batches · up to 160,000 images
  • Priority lane on the L40S GPU
  • Unused credits roll over a month
  • K Agent runs 50 batches at once
  • Unlimited K Agent chats
  • Unlimited LoRA and checkpoint uploads
  • Dark Lord looks: hellfire, thorns, runes
  • 2 API streams at once
  • + Everything the API tier has
  • + 50 GB of Files hosting
Choose Dark Lord
King
$99.99/ month
25,000 credits / month
~50,000 batches · up to 400,000 images
  • Unused credits roll over two months
  • A monthly gift pass: a month of Elite for a friend
  • Every King look: crowns, gold names, effects
  • 4 API streams at once, no prompt-length cap
  • Unlimited LoRA and checkpoint uploads
  • + 100 GB of Files hosting
Choose King
1

Pick a tier. Every plan includes the generator, the Roleplay API and Files hosting, and each one includes everything in the plan before it.

2

Choose how to pay. Card, crypto or Boosty. Payment stays with the processor. We never see your card.

3

Sign in and generate. Your credits are live within a minute. Cancel any time from the platform you paid on.

There is also a free tier for trying the generator, and a lighter plan if you only need the basics.

Questions.

Batch mode sends your prompt to a shared GPU pool that returns up to eight images at once for a flat 0.5 credits, whatever the resolution or count. Standard mode runs on a dedicated endpoint with full LoRA support and slightly faster per-image generation. Use Batch for volume and Standard for control.
You give it a character description and a scenario. A planning model of your choice (GLM, Qwen, Kimi or DeepSeek) writes a fresh Danbooru-tag prompt for every batch and keeps each one different from the last, and the image model renders it. That repeats 5, 20 or 50 times. Planning mode drafts every scene first, so you can edit before any image is generated.
On Dark Lord and King, yes: what you have not used carries over for one month on Dark Lord and two on King, and is spent before the new month's credits. On the other plans credits reset to the full amount every 31 days. If you upgrade mid-cycle the higher quota applies immediately.
HQ mode swaps in the full-precision version of AniCoreXL, layers two LoRAs on top and runs Ultimate SD Upscale at 1.4x with seam fixing. The result is roughly 1.4x your chosen resolution with noticeably more detail. It costs 3 credits an image and is capped at two images a generation.
Yes. Every image generated here carries its full configuration (prompts, model, steps, CFG, dimensions, LoRAs and strengths) in a text chunk inside the PNG. Drop any of them back into the import dialog and the settings restore exactly. Your last 100 prompts are also kept and can be applied with one click.
Kyrune is a general audience service. Sexual content is not allowed here, generated, uploaded or published, and content involving minors is prohibited without exception. What you may and may not make, how it is enforced, how to report something and how to appeal are set out in the Content Policy. Your gallery and prompt history live in your own browser, or in your private cloud bucket if you turn on cloud save.
Boosty subscribers sign in through Discord. Connect your Boosty subscription to your Discord account, join the Kyrune Discord server and the bot assigns your tier role automatically. Then choose the Boosty/Discord button on the login screen. Setup guide

Start with your first batch.

Every plan includes the generator, the Roleplay API and Files hosting. Pay by card, crypto or Boosty, and cancel any time.

Every model.
One key.

Plug Kyrune into Chub.ai, JanitorAI, SillyTavern or any OpenAI-compatible client and get GLM-5, DeepSeek V4 Pro, Kimi K2.6, Euryale, Magnum and more than 25 other models, with a median two seconds to the first token.

Requests served
1,038,081
1,217 creators · 30+ models · ~2s median time to first token
Live API feed
A live feed of real requests, anonymised server-side. Not a simulation.

Connect the app you chat in

Pick JanitorAI, Chub, SillyTavern or your own code, and the dashboard shows you exactly what to paste where.

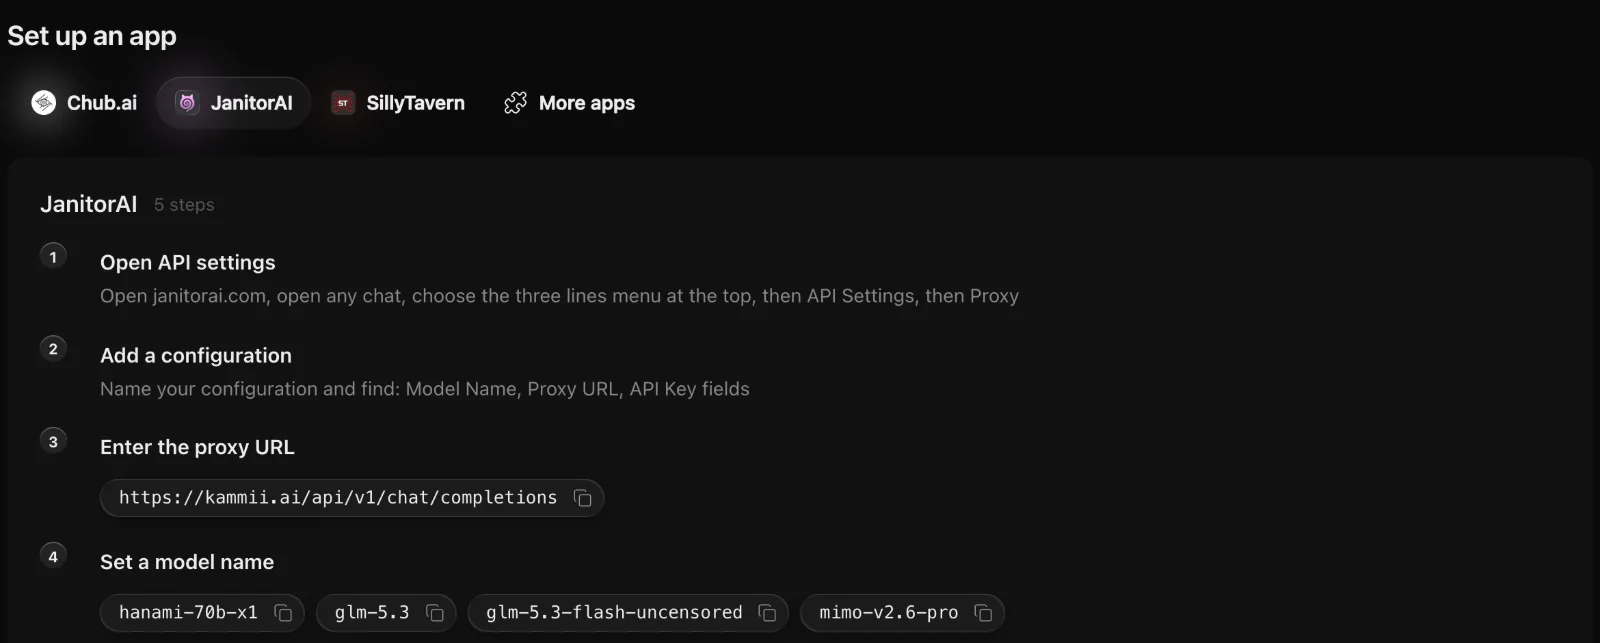
In JanitorAI, open the API settings and choose a proxy. Copy the URL and a model name from this screen, then paste your Kyrune key.

The Set up an app screen in the Kyrune API dashboard, with the proxy URL and model names

Streaming that starts
in about two seconds.

Every request goes through Kyrune's response engine, tuned for time to first token. Most replies start streaming in about two seconds, whatever the model size. Short failures are retried before your client ever sees a broken stream.

Response-time illustration · example values
Lightning models
0.0s
GLM-4.7 Flash · Mistral Nemo · Hermes 4.3 36B
Standard models
0.0s
Euryale 70B · Magnum v4 72B · Hanami 70B
Frontier base models
0.0s
GLM-5 · DeepSeek V4 Pro · Kimi K2.6
Heavy reasoning
0.0s
DeepSeek R1 · Kimi K2 Thinking · Qwen3 235B Thinking

Three differences from a metered service.

Each one is something you can check for yourself.

01

A flat monthly price.

Sponsor and above get unlimited roleplay messages. Chat for eight hours, write a 200-message epic, regenerate the same scene thirty times. The monthly price does not move.

Pay-per-token services ~$0.50 per long reply
Kyrune Sponsor+ Flat monthly, $0 per reply
02

Derestricted model variants.

Derestricted GLM, DeepSeek and Hermes variants with hand-tuned roleplay prompts, and a thinking mode you switch per model that does not talk itself out of answering.

03

Setup is three lines.

Three lines of configuration. The same key works in JanitorAI, Chub, SillyTavern and your own code, and switching models is a one-string change with no new login.

URLapi.kammii.org/v1
KEYkammii-xxxxxxxxxx
MODELglm-5

Roleplay fine-tunes and frontier models.

Roleplay-tuned 70B fine-tunes for character consistency, and frontier mixture-of-experts models when you need raw intelligence. Both are curated.

Roleplay models

Llama 3.3 70B and Qwen 2.5 72B fine-tunes

  • Euryale 70B v2.3 · Long-form roleplay
  • Magnum v4 72B SE · Literary prose, dark themes
  • Hanami 70B x1 · Euryale lineage, fewer stock phrases
  • Anubis 70B v1.1 · Strong character voice
  • Cirrus 70B x1 · Refined, stable, creative
  • Fallen Llama 70B v1 · Reasoning plus roleplay
  • Forgotten Abomination v5.0 · Unaligned
  • SorcererLM 8x22B · Rich vocabulary on WizardLM
Best for character chats and long sessions

Frontier models

Mixture-of-experts models up to 1.6T parameters

  • GLM-5 · 744B, our pick
  • GLM-5.1 · 355B, the latest
  • DeepSeek V4 Pro · 1.6T, 1M context
  • Kimi K2.6 · 1T, multimodal
  • GLM-4.7 · 355B, interleaved thinking
  • DeepSeek V3.2 · Speciale variant
  • Qwen3.5 397B · The latest Qwen
  • Hermes 4 405B · Reasoning-focused
  • MiniMax M2.5 · and more
Best for complex tasks, smart roleplay and agents
Turn on Thinking mode on supported models for chain-of-thought reasoning, or use the raw variants to bypass the presets entirely.

Every setting, in one dashboard.

Presets, parameter sliders, model swaps, encryption and live capacity meters. None of it needs code.

Per-model parameters

Override temperature, top_p, top_k, min_p and repetition penalty, saved separately for every model. GLM-5 gets quick-tune sliders with Wild, Balanced and Coherent presets.

Temperature
1.05
Top P
0.95
Min P
0.03
Rep penalty
1.05

Preset library

Geechan's General RP, Simplified RP or your own system prompt. Click to apply. The preset stays attached to every model variant except -raw.

Geechan's General Roleplay ~700 tokens
Simplified Roleplay ~450 tokens
Custom (yours) edit →

Live stats dashboard

Daily, weekly and monthly usage, tokens by model, top platforms, recent conversations and median latency across the catalog. Per account, never aggregated.

Today
42
This week
287
This month
1.2K

Swap models mid-conversation

Change one string in your client (glm-5 to kimi-k2.6) and you are on a different model. Same key, same conversation, same context.

glm-5 kimi-k2.6
No re-auth · same key

Stateless relay, end-to-end encrypted.

Kyrune is a stateless relay. Your messages live in memory for the milliseconds it takes to pass them on. They are never written to disk, logged or indexed, and with end-to-end encryption on, even our own infrastructure cannot read them. Encryption is AES-256-GCM and switches on in the dashboard. There are no analytics scripts, tracking pixels or fingerprinting.

1 Your message encrypted in browser
2 Relayed to model in memory
3 Response decrypted at your device
4 Memory wiped after the response

New models most weeks.

Every model ships with tuned presets and per-model overrides. Use the -raw variants when you would rather control everything yourself.

From key to first message in three minutes.

Sign in, generate a key and paste it into your client. The same key works on every model in the catalog.

Generate your key

Sign in with your Kyrune account, or with Boosty through Discord, choose Generate Key and copy your kammii-... token from the dashboard.

Paste it in your client

Set https://kyrune.red/api/v1 as the reverse proxy, paste the key and pick a model name such as glm-5 or euryale-70b-v2.3.

Chat

Responses stream token by token. Change presets, switch thinking mode on or off and swap models mid-conversation, all with the same key.

from openai import OpenAI

client = OpenAI(
    api_key="kammii-xxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxx",
    base_url="https://kyrune.red/api/v1"
)

stream = client.chat.completions.create(
    model="glm-5",
    messages=[{"role": "user", "content": "Continue the story..."}],
    stream=True
)

for chunk in stream:
    print(chunk.choices[0].delta.content or "", end="")

What the dashboard holds.

Presets, per-model parameters, encryption and full usage statistics.

Custom presets

Override the default system prompt for roleplay or base models, or pick from the curated library: Geechan's General RP, Simplified RP and more.

Per-model parameters

Edit temperature, top_p, top_k, min_p and repetition penalty, saved per model, with quick-tune sliders for GLM-5.

Thinking mode

Turn reasoning on for GLM, DeepSeek, Kimi, Qwen and Hermes to get the chain of thought before the reply, or skip it for speed.

End-to-end encryption

With AES-256-GCM on, messages are encrypted before they leave your browser. Only the model sees plaintext.

Usage dashboard

Daily, weekly and monthly usage, tokens by model, top platforms, recent conversations and average latency. Per account, never aggregated.

Zero retention

The relay is stateless. A conversation exists in memory only for the milliseconds it takes to pass it on. Nothing is logged and nothing is stored.

One subscription, three services.

Every API tier includes Image Gen and Files hosting with the matching allowance. Sponsor and above get unlimited roleplay messages, and each tier includes everything in the one before it.

Supporter
$4.99/ month
50 requests / day
  • All roleplay and base models
  • 16K context limit
  • Custom presets
  • Stats dashboard
  • + 500 Image Gen credits
  • + 5 GB of Files hosting
Choose Supporter
Sponsor
$11.99/ month
Unlimited roleplay
  • 100 requests a day on base models
  • 20K context limit
  • + 1,500 Image Gen credits
  • + 12 GB of Files hosting
Choose Sponsor
Dark Lord
$49.99/ month
Maximum usage
  • 2 streams at once
  • Beta model access
  • Custom integration help
  • + 10,000 Image Gen credits
  • + Everything the Image Gen tier has
  • + 50 GB of Files hosting
Choose Dark Lord
King
$99.99/ month
4 streams at once
  • No prompt-length cap
  • Requests stay off the public live feed
  • A monthly gift pass for a friend
  • + 25,000 Image Gen credits
  • + 100 GB of Files hosting
Choose King

A free tier with 10 requests a day and a lighter plan are also available. Both include Image Gen credits and Files hosting.
Subscribe through Boosty.

Compare models side by side

We sent the same roleplay message to glm-5.3 and hanami-70b-x1. Read both replies and pick the one that suits your character. Switching models never needs a new key.

glm-5.3first token 4.2 s · 70 tok/s

Mira looked up from the ledger she'd been half-heartedly closing, her reading glasses slipping down her nose. The lamp on the counter threw warm, amber light across the stacks, and somewhere deeper in the shop a clock ticked its steady, patient rhythm. She took in the rain-dark coat, the apologetic posture, and smiled, the particular smile of someone who never truly minded staying late when the alternative was an empty evening.

"You're fine," she said, marking her place in the ledger with a dried fern frond. "The books don't keep hours, and neither do I, apparently." She gestured toward the rows of spines gilded in lamplight, the narrow aisles that smelled of old paper and salt air drifting through the gaps in the window frame. "Come in. There's tea if you want it, and a radiator in the back corner that actually works."
hanami-70b-x1first token 3 s · 18 tok/s

The bell above the door jingled as it swung shut behind her, the sound mingling with the patter of raindrops on the shop's tin roof. Mira looked up from behind the counter where she sat hunched over a book, a pair of reading glasses perched on the end of her nose. She smiled, marking her place in the novel before setting it down.

"Of course we're still open," Mira said warmly as she stood to greet the damp customer. "You know I'm always happy to help anyone seeking refuge from that nasty weather outside. Come on in and take a look around - maybe something will catch your eye." With an encouraging nod, she gestured to the shelves stacked high with volumes of every shape and size, their leather spines gleaming softly under the glow of lamplight. The scent of old paper and ink enveloped them like a familiar embrace, inviting exploration of the cozy little bookshop's nooks and crannies.

Questions.

Most services are metered: you pay per token, manage a balance and hit refusal filters on some models. Kyrune is built for roleplay. Every model is curated with tuned presets, you get thinking-mode toggles, encryption, per-model parameters and a clean dashboard, and Sponsor and above chat without a meter.
The response engine handles capacity for you. If your model is at capacity the request is retried on alternate infrastructure and you see one continuous stream. The dashboard shows live capacity for every model, so an overloaded one is visible before you send.
Kyrune is stateless. Messages are processed in memory for the milliseconds it takes to relay them and are never written to disk, logged or stored. We count message structure (the number of user and assistant turns) for usage statistics, but never read content. With end-to-end encryption on, even our infrastructure cannot see plaintext. Content involving minors is prohibited without exception.
Some models, Cirrus 70B and Anubis 70B among them, have only one or two concurrent streams across all users. If everyone is generating at once your request may be rejected. Wait a few seconds and retry. Models marked Uninterruptible have unlimited concurrency, and the dashboard shows live capacity for each one.
The plain model name uses our tuned temperature, sampler and a system prompt added at the end of your conversation. The -raw variant bypasses all of it, so your client's settings go straight to the model. Use raw when you have your own preset and want full control.
Yes. The dashboard has a Request a Model panel. Paste a Hugging Face link to a publicly available full-precision model between 8B and 70B and we will consider it. Most approved requests are live within a week, and Sponsor and above get priority.
Yes. One Boosty subscription unlocks all three services at your tier. Image Gen credits and API request quotas are separate allowances, and Files hosting is included on every tier.
Anything that speaks the OpenAI API. Setup is tested and documented for JanitorAI, Chub.ai and Venus, and SillyTavern. Your own code in Python, Node, Go or anything else that posts JSON works with the standard OpenAI SDK by swapping the base URL.

One key for every model.

Unlimited messages on Sponsor and above, streaming that starts in about two seconds, and a setup that takes three minutes. Cancel any time.

From prompt to character card.
Watch it happen.

Generate art in Image Gen, host it on Files and paste a Markdown link into SillyTavern or Chub.ai. Your roleplay gets pictures. Scroll to watch the whole flow.

Generate the shot.

Start in Image Gen. Pick a model, type a Danbooru-style prompt and generate. Batch mode returns eight variations a request, and AutoGen runs whole series unattended.

Upload and optimise in one step.

From the result, choose Save to Files. The image is encrypted, uploaded to your private gallery on files.kammii.org and converted to WebP in seconds, up to 89% smaller at 99% of the visual quality.

Served from the edge, worldwide.

Your file is pushed to more than 200 edge locations. Wherever your reader is, the nearest one answers in under 50 ms, with 99.99% uptime.

Browse your gallery.

Every upload lands in your private dashboard. Name galleries, mark them public or private, add files any time and build a permanent library of character art.

Inspect the metadata.

Choose the i button on any Kyrune-generated image and the metadata panel slides in: positive prompt, negative prompt, every parameter, the exact model and seed.

Regenerate in one click.

Choose Generate with these settings and you are back in Image Gen with every parameter filled in: prompt, model, seed range, sampler and detailer. Tweak something, or generate fresh variations of the same look.

Copy the Markdown.

Pick your favourite from the new batch, hover, and choose the [ ] button. The Markdown snippet is on your clipboard.

Paste into your card.

Open your character editor in SillyTavern, Chub.ai or JanitorAI and paste the Markdown into a greeting or description. The image embeds inline, every time.

kammii.ai/gen
PROMPT
kana_arima, 1girl, pink t-shirt, blush, looking_at_viewer, masterpiece, best quality
ModelAniCoreXL v5
Batch×4
Size1024×1024
RESULT · 4 images
files.kammii.org
Encrypted upload · SSIM-guided WebP
PNG2,048 KB
WebP220 KB
PNG
2,048 KB
WebP
2,048 KB
−89% smaller · SSIM 0.99 · visually identical
Edge network
files.kammii.org · cached worldwide
0+
PoPs
99.99%
Uptime
<50ms
p95
120+
Countries
Kana Arima
Public · 12 files
NEW
Ruby Hoshino
Private · 8 files
Mood Board
Public · 24 files
Side Characters
Private · 15 files

Image Metadata

Positive Prompt
masterpiece, best quality, very aesthetic, absurdres, 1girl, teen, modern, deep black hair, straight hair, slim, black stud earrings, medium sized breasts, green eye pupils, black nails, (bags under eyes:0.8), green eyes, hime cut, hair between eyes, close-up, wearing viewer oversized hoodie, hood up, sleeves past hands, pouty expression, indoor, cozy home, looks adorable while annoyed, borrowed clothes, domestic intimacy
Negative Prompt
worst quality, low quality, signature, lowres, (bad), bad hands, text, error, fewer, extra, missing, jpeg artifacts, watermark, unfinished, displeasing, oldest, early, chromatic aberration, signature, extra digits, artistic error, username, scan, censor bars, deformed legs, deformed limbs, green hair, colored hair, extra legs
Parameters
Steps
30
Size
1080×1624
Sampler
Euler a
Seed
60643253508963
CFG scale
5.0
Batch
1×3
App
SD.Next
Model
KAI_illustrious_v2
Detailer
face-yolo8n
Det. steps
99
Settings imported from kana_arima.png
PROMPT · restored
masterpiece, best quality, very aesthetic, absurdres, 1girl, hime cut, deep black hair, green eyes, oversized hoodie, hood up, pouty expression, cozy home...
ModelKAI Illustrious v2
Steps30
CFG5.0
Detailerface-yolo8n
FRESH BATCH · 4 images
Galleries › Kana Arima › New Batch
WEBP · 480 KB
Copied to clipboard
First Message
1 / 3
Auto-saved

Generate Save Distribute Browse Inspect Regen Copy Paste

Made for character creators.

These features move your art into the platforms you already use.

Galleries Put pictures in folders and share a whole folder with one link. Everything stays private until you share it.
WAI Illustrious v17solo, 1girl, anthro rabbit, white fur, pink eyes, white cloak, hood up …
Reader view Open a picture to see it next to its prompt and model, and copy either with one click.
Supporters see this
Preview mode Show everyone a blurred teaser and let your supporters see the full picture.

Questions.

No. Files hosting is included with every Kyrune tier, including Free. No extra cost, no separate quota, no separate login.
Images (PNG, JPEG, WebP, GIF), video (MP4, WebM, MOV), audio (MP3, WAV, OGG, FLAC) and most other file types. WebP optimisation is offered at upload.
Public links stay live as long as the file is on Kyrune. Active subscribers can manage, delete or download their whole library at any time.
Yes, when you upload with Original Format selected. Choose the i button on any image in Files to view the full configuration, or Generate with these settings to reopen it in Image Gen.

Hosting is included.

Files comes with every Kyrune tier. Sign in and start uploading in under a minute.